Benefits
Accelerate property transactions by moving from manual data entry to automated extraction of title numbers, parcel IDs, and owner details in seconds.
Reduce risk in conveyancing and mortgage processing with consistent, auditable extraction of registration dates, sale prices, and transaction dates.
Eliminate the bottleneck of re-keying data from scanned deeds and official copies, freeing legal and property professionals for higher-value work.
Support compliance workflows, from anti-money-laundering checks to land registry updates, with structured data that flows directly into your case management or ERP system.
How it works
- Step 1
Upload
Send the document to the API as a file or a URL no special formatting required.
- Step 2
The engine reads the document
The engine analyzes the page layout and identifies the content that matters. ByteIt's extraction engine reads the structured layout of land registry documents, including title registers, property descriptions, ownership tables, and transaction records, to identify and extract property, owner, and transaction fields.
- Step 3
Structured JSON is returned
Every extracted element comes back as structured JSON, positioned and typed, ready to feed into downstream systems.
- Step 4
Confidence-based review
Each field carries a confidence score, so low-confidence results can be routed for human review instead of trusted blindly.
Example fields
A sample of what extraction can return, and many more when they appear on the document.
Features
Extracts fields from land registry documents such as property description, parcel ID, owner name, title number, registration date, area size, sale price, transaction date, and many more.
Accepts scanned PDFs, photographs of paper deeds, and native digital documents in JPG, PNG, PDF, and other common formats.
Provides structured output in JSON, ready for integration with property management software, conveyancing platforms, or workflow automation tools.
Handles multi-page documents such as lengthy title registers and official copies with multiple folios.
Processes documents in multiple languages and regional land registry formats, supporting jurisdictions across the US, UK, and EU.
Use cases
Title verification during conveyancing
When a property changes hands, solicitors must verify the title register, check ownership records, and confirm registration dates. ByteIt's extraction reads the title number, owner name, and property description from the official copy, feeding structured data into your conveyancing case management system to flag discrepancies before exchange of contracts — always verified by a human before any decision.
Portfolio reconciliation for property funds
Property funds manage hundreds of titles across multiple jurisdictions. By extracting parcel IDs, area sizes, and ownership types from land registry documents, the fund's back office can reconcile holdings against its asset register without manually opening each deed, with data piped into an ERP or property management system via workflow automation tools like n8n or Make.
Mortgage underwriting and compliance checks
Lenders require proof of ownership, title number, and any encumbrances before approving a mortgage. ByteIt extracts the relevant fields from the official copy, including transaction date and sale price, and sends them to the underwriting platform, reducing the time from application to offer — always verified by a human before any decision.
Land registry data migration and system consolidation
When a government agency or large landowner modernises its record-keeping, legacy paper deeds and scanned registers must be digitised. ByteIt's batch processing converts historical land registry documents into structured data for import into a new GIS or land information system, preserving fields like coordinates, parcel ID, and property type.
Automated property tax and valuation workflows
Valuation offices and tax authorities need up-to-date sale prices, transaction dates, and area sizes from registered titles. Extracted data can be routed directly into valuation models or tax assessment systems, eliminating the need to manually pull figures from scanned deeds.
LIVE DEMO
Try it yourself
Upload a sample land registry document, a title deed, official copy, or property register, in PDF, JPG, or PNG format and see ByteIt extract the key fields in real time.
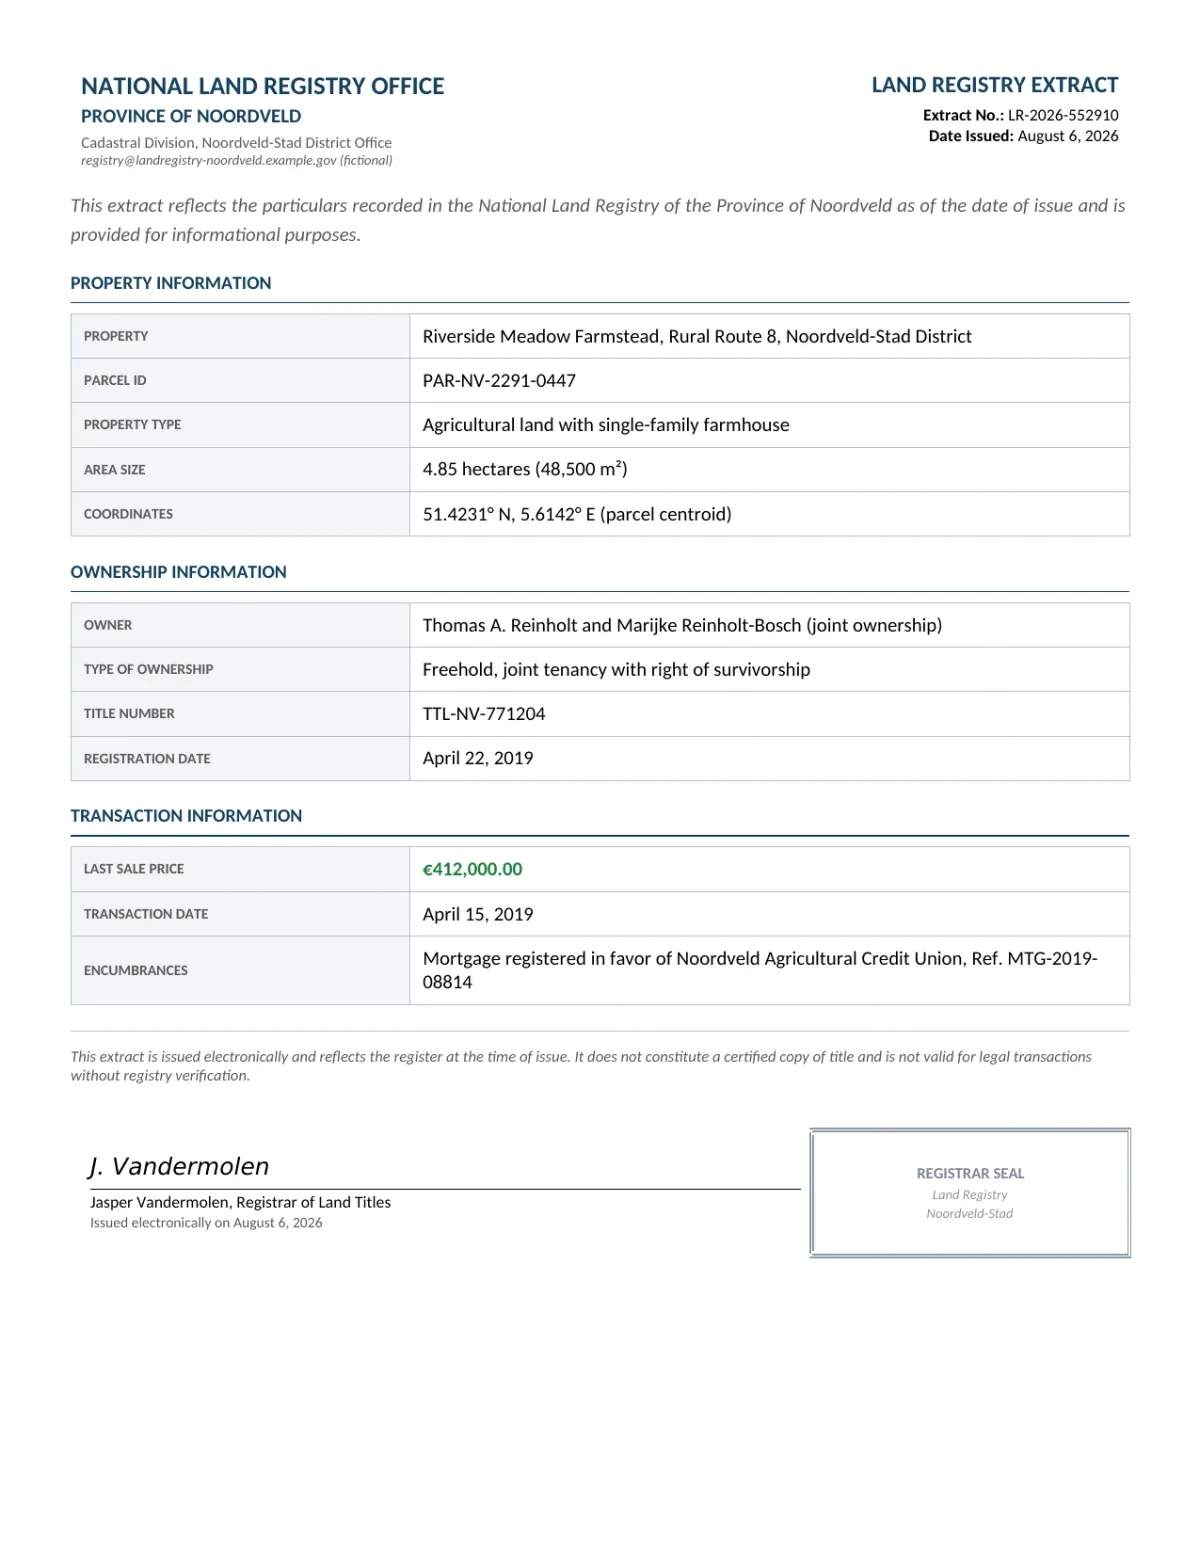
Select a document and press Parse
Want to run it on your own documents?
Ready to dive in? Request a key to get started.Business advantages
- No per-document minimum, no hidden overage fees.
- European-hosted infrastructure with GDPR-compliant data handling.
- Works with low-quality scans and mobile photographs of paper deeds.
- Returns structured JSON output, ready for any downstream system.
Frequently asked questions
How does pricing work for land registry document extraction?
ByteIt offers usage-based pricing with no minimum commitment. You pay per document page processed, with volume discounts available at higher tiers. Check the pricing page for current rates.
How do I integrate the extraction into my conveyancing or property system?
ByteIt provides a REST API and client SDKs for Python, JavaScript, and other languages. You can also connect the extraction to your workflow using no-code automation tools like Zapier, Make, or n8n, no engineering team required for basic integrations.
What file formats are supported for land registry documents?
The API accepts PDF, JPG, JPEG, PNG, TIFF, and HEIC files. Both single-page and multi-page documents are supported, making it suitable for lengthy official copies and title registers.
Does it work with low-quality scans or photographs of paper deeds?
Yes. The engine is trained to handle variable lighting, angled photos, and imperfect scans common with older paper deeds. For best results, ensure the document text is legible and the full page is visible.
Can it process multi-page title registers and official copies?
Yes. ByteIt handles multi-page documents by processing each page and consolidating the extracted fields into a single JSON output. This is especially useful for lengthy title registers that span dozens of pages.
What is the typical extraction accuracy for land registry data?
Accuracy depends on document quality and layout. On standard, legible official copies and title deeds, the engine achieves high extraction quality for structured fields such as title number, property address, and owner name. Complex handwritten annotations or heavily faded scans may reduce accuracy.
Related documents
Property Appraisal Reports
Extract structured data from property appraisal reports, appraised value, comparable sales, property condition, and more. OCR for URAR, 1004, and custom forms.
Energy Certificates
Extract structured data from energy certificates with ByteIt's AI engine. Capture energy labels, consumption data, GHG ratings, and more from PDFs and images.
Flood Certificates
Extract flood zone, BFE, property details, and community data from flood certificates automatically. API for lenders, insurers, and floodplain managers.
Chamber Of Commerce Extract
Extract key fields from Chamber of Commerce extracts automatically. Pull company name, CoC number, legal representatives, entity type and more via API.
Proof Of Residence
Extract structured data from proof of residence documents. AI-driven OCR reads utility bills, bank statements, lease agreements and more for KYC compliance.