Benefits
Eliminates manual data entry from formation documents, saving hours per filing and reducing transcription errors that can lead to compliance gaps
Accelerates entity onboarding and KYC workflows by turning paper or PDF filings into structured data in seconds
Supports multi-state and multi-jurisdiction filings without reconfiguring templates, because the engine reads the document rather than relying on positional form fields
Enables downstream automation, push extracted corporate data into entity management software, CRMs, or governance platforms via API or workflow tools
How it works
- Step 1
Upload
Send the document to the API as a file or a URL no special formatting required.
- Step 2
The engine reads the document
The engine analyzes the page layout and identifies the content that matters. reads the articles of incorporation as a whole document and identifies all declared clauses, corporate name, purpose, share structure, registered agent, incorporators, director appointments, indemnification provisions, regardless of layout or jurisdiction-specific form design.
- Step 3
Structured JSON is returned
Every extracted element comes back as structured JSON, positioned and typed, ready to feed into downstream systems.
- Step 4
Confidence-based review
Each field carries a confidence score, so low-confidence results can be routed for human review instead of trusted blindly.
Extractable fields
Features
End-to-end OCR pipeline purpose-built for legal filings, handling both typed and handwritten text on variable-form layouts
Extracts corporate identifiers including company name, state of incorporation, filing date, filing number, and entity type
Captures capital structure details: authorised shares, par value, share classes (common, preferred), and currency
Reads registered agent name and address, incorporator details, initial directors, and indemnification/liability limitation clauses
Returns structured JSON with all extracted fields, ready to integrate into entity management and compliance systems
Use cases
Entity management and corporate record keeping
Corporate paralegals and entity management teams need to maintain accurate records for every legal entity in a corporate structure. With ByteIt, articles of incorporation are processed on receipt, the corporate name, state of filing, share structure, registered agent, and incorporator data are extracted and pushed directly into entity management platforms such as Diligent Entities, GEMS, or internal databases, eliminating manual file reviews that take 45–60 minutes per filing.
Investor due diligence and deal execution
When evaluating a target company, investment firms, M&A advisors, and legal counsel must verify the authorised capital structure, the existence of multiple share classes, and the entity's good standing in its state of incorporation. ByteIt extracts the exact share authorisation from the filed charter and cross-references it against the cap table, flagging discrepancies before they delay a closing. The structured output can feed directly into virtual data rooms and due diligence checklists.
KYC and AML compliance for financial institutions
Banks, fintechs, and payment processors require verified legal entity data when onboarding corporate customers. Articles of incorporation provide the authoritative source for the legal name, registered address, and authorised signatory structure. ByteIt's extraction API converts these filings into machine-readable data that can be piped into AML screening systems and customer due diligence workflows, reducing manual verification steps and accelerating onboarding from days to minutes.
Corporate governance and director tracking
Governance teams must track initial director appointments and any subsequent changes across a portfolio of entities. ByteIt extracts the initial directors named in the articles of incorporation, including their full names and addresses, enabling automated population of director registers and conflict-of-interest databases. When articles are amended or restated, re-processing the document updates the record without re-keying.
Downstream integration with workflow automation
Extracted corporate data can be connected to downstream systems through general workflow automation tools such as n8n, Zapier, or Make. For example, when a new articles of incorporation is processed, the extracted fields can trigger a new entity record in a CRM, notify the compliance team, generate a filing checklist, and populate a portfolio dashboard, all without manual intervention.
LIVE DEMO
Try it yourself
Upload a sample articles of incorporation in PDF, JPG, or PNG format and see the extracted fields returned as structured JSON in real time.
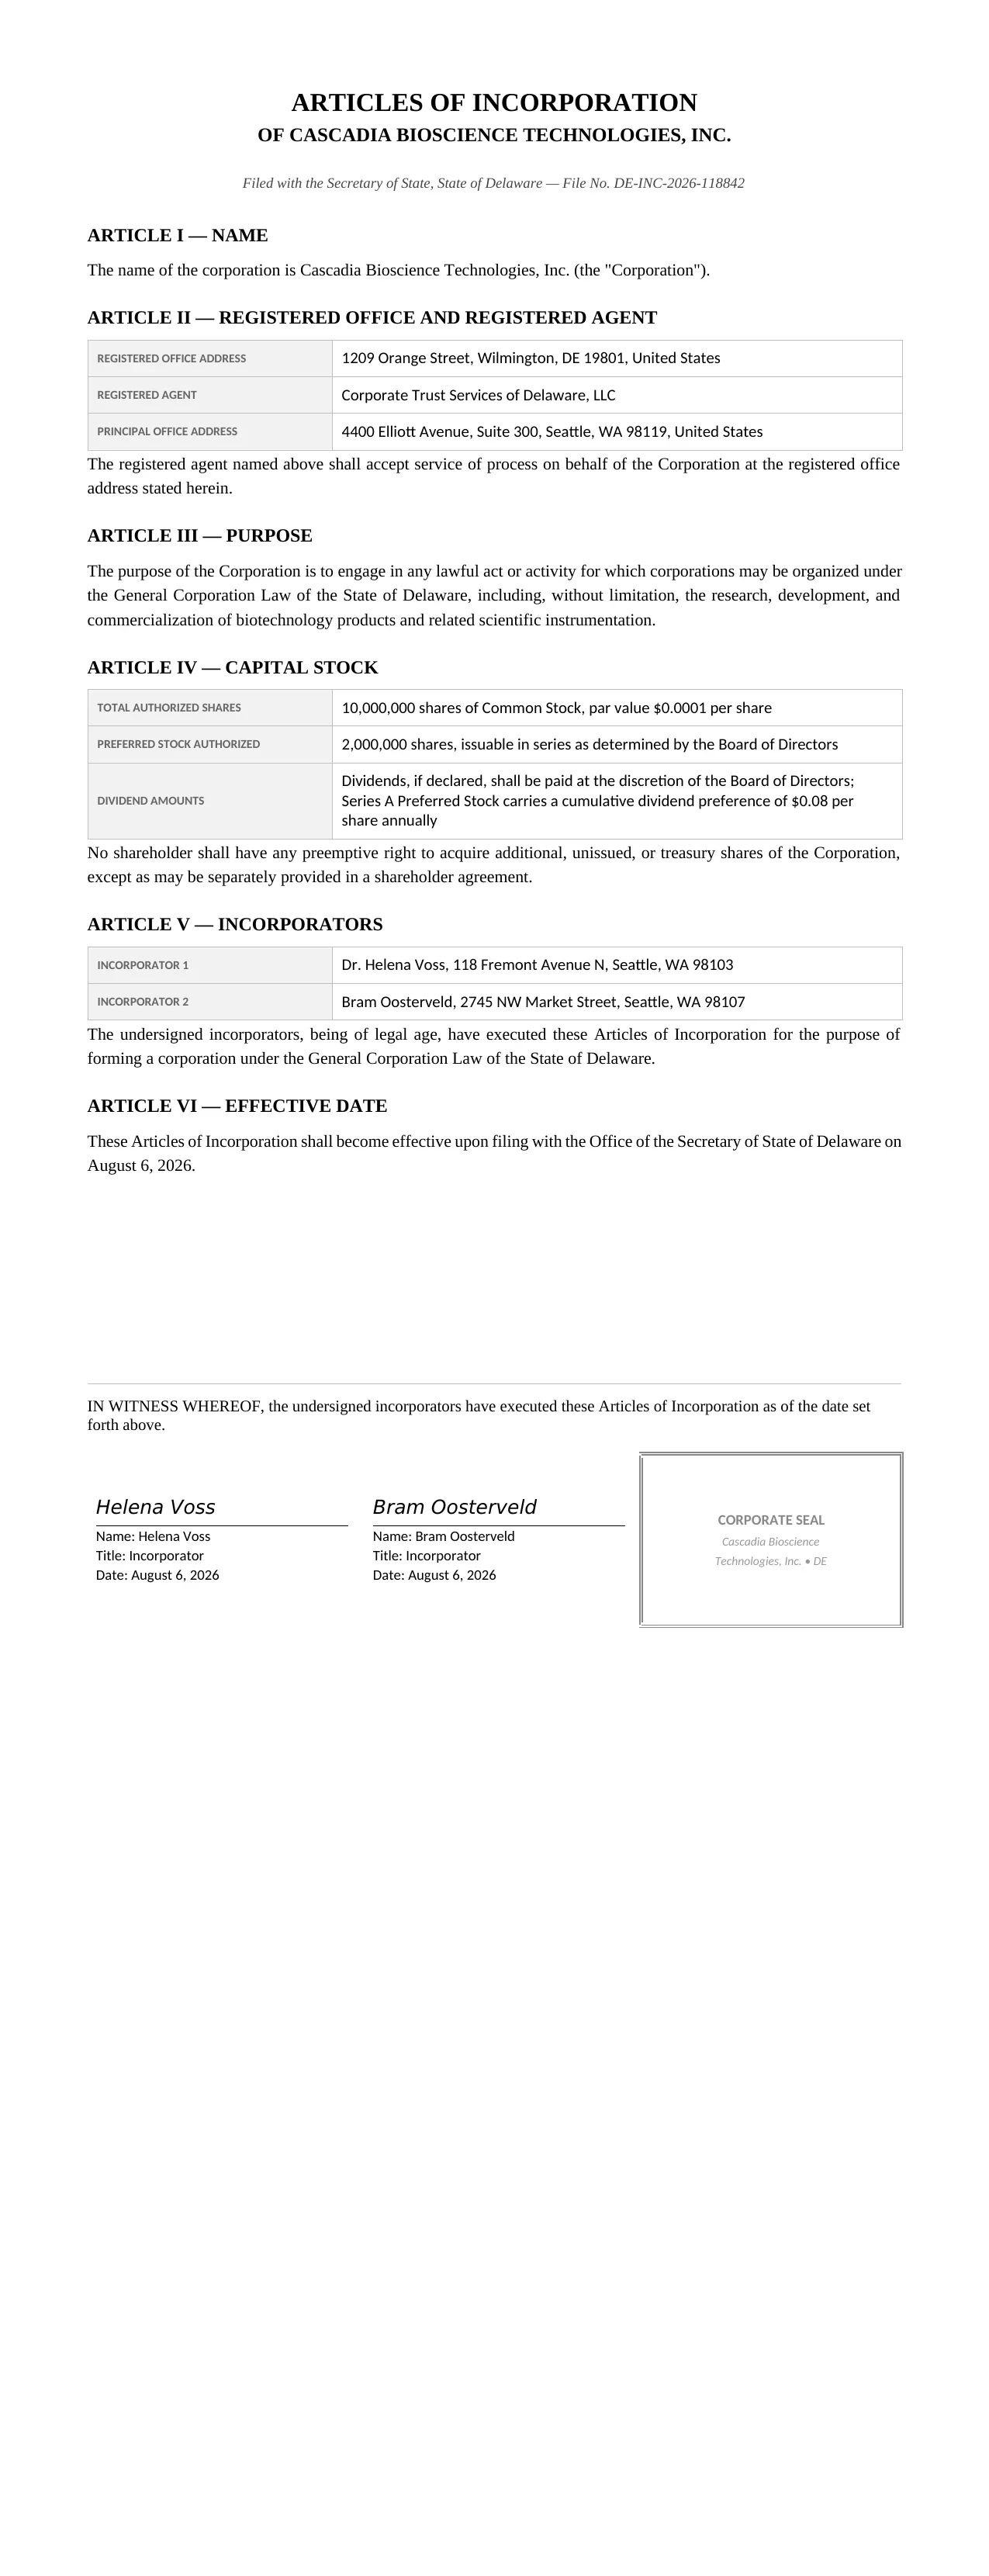
Select a document and press Parse
Want to run it on your own documents?
Ready to dive in? Request a key to get started.Business advantages
- Reads any filing layout, no template setup needed
- Structured JSON output for instant integration
- Handles multi-page filings with amendments and restatements
- Supports US and European corporate filing formats
Frequently asked questions
How does ByteIt price articles of incorporation extraction?
Pricing is based on document pages processed through the API, not on the number of fields extracted. You pay per page, and there are no separate charges for additional data points, the full extraction is included. Volume discounts are available for high-throughput legal and compliance operations. Check the ByteIt pricing page for current rates.
How do I integrate the articles of incorporation extraction into my workflow?
ByteIt provides a REST API that accepts document uploads and returns structured JSON. You can integrate it directly into your application using any HTTP client, or connect it to no-code workflow platforms like n8n, Zapier, or Make for automated processing pipelines without writing code.
What file formats are supported?
The API accepts PDF, JPG, PNG, and TIFF files. Both single-page and multi-page documents are supported, including filings that span multiple pages with schedules and attachments.
How does ByteIt handle low-quality scans or faded filings?
The extraction engine includes pre-processing steps that correct skew, adjust contrast, and enhance text legibility before extraction. It is designed to handle scanned paper filings, microfilmed records, and documents with varying print quality common in older corporate records.
Can it process multi-page filings that include amendments and restatements?
Yes. The engine reads the entire document across all pages and can identify multiple effective dates, restated provisions, and amendment records within a single filing. Each section is extracted with its corresponding effective date where present.
What extraction accuracy can I expect for articles of incorporation?
Accuracy depends on document quality and layout complexity. ByteIt's engine is trained on a wide variety of legal filing formats and consistently achieves high precision on standard fields such as company name, state of incorporation, share structure, and registered agent details. We recommend testing with your own document set to validate accuracy for your specific filing sources.
Does the API extract share class details like par value and voting rights?
Yes. The engine extracts authorised share counts per class (e.g. Common, Preferred Series A), par value per share, and the currency denomination. Class-specific provisions such as voting rights, dividend preferences, and conversion terms are captured when present in the document.
Related documents
Contracts
Extract parties, contract clauses, signatures, and applicable law from legal contracts using ByteIt's structured data extraction API. Supports PDFs and scanned documents.
Bylaws
Extract structured data from corporate bylaws with AI-powered OCR. Capture entity names, committee structures, conflicts of interest and more via API.
Rental Agreements
Extract tenant details, rent amounts, escalation schedules, and key clauses from residential and commercial rental agreements. AI-powered OCR for any lease format.
Permits
Extract structured data from building permits, environmental permits, and regulatory licences with AI. Capture dates, signees, clauses, risk keywords, and more.
Insurance Claims
Extract structured data from insurance claim forms and supporting documents automatically. Claimant details, policy numbers, loss descriptions and more in seconds.