Benefits
Significantly reduce diploma verification time with instant data extraction
Eliminate manual data entry errors when transcribing graduate names, degree details, and institution information
Speed up hiring and onboarding by feeding verified credential data directly into your HRIS or ATS
Scale credential processing across hundreds or thousands of diplomas without adding headcount
How it works
- Step 1
Upload
Send the document to the API as a file or a URL no special formatting required.
- Step 2
The engine reads the document
The engine analyzes the page layout and identifies the content that matters. The engine reads both printed and handwritten text on diplomas, including graduate names, institution details, diploma numbers, issuing dates, and field of study, while preserving the spatial layout of the original document.
- Step 3
Structured JSON is returned
Every extracted element comes back as structured JSON, positioned and typed, ready to feed into downstream systems.
- Step 4
Confidence-based review
Each field carries a confidence score, so low-confidence results can be routed for human review instead of trusted blindly.
Example fields
A sample of what extraction can return, and many more when they appear on the document.
Features
Extracts fields such as graduate name, date of birth, institution name, diploma number, issuing date, field of study, signature, institution logo, and many more.
Handles diplomas in PDF, JPG, and PNG formats, including scanned paper documents and digital certificates
Pre-built SDK integrations for Python, Node.js, Java, and other major languages
Handles a range of scan qualities, including skewed angles and varying lighting common in archived academic documents
Use cases
Employee Onboarding & Background Verification
HR teams receive hundreds of diploma copies during onboarding. ByteIt extracts the graduate name, institution name, issuing date, and diploma number in seconds, so verification teams can cross-check against university records without manually retyping every document.
Academic Credential Fraud Detection
Recruitment teams and credential verification agencies process applicant-provided diplomas through ByteIt to extract structured data fields. By comparing extracted details against known institution formats and diploma number patterns, teams can flag suspicious documents for deeper investigation.
University Transcript Digitisation
Educational institutions with decades of paper diploma archives can digitise and structure their entire repository. ByteIt extracts student name, date of birth, field of study, and diploma number from scanned originals, making decades of records searchable by any field.
Professional Licensing & Regulatory Compliance
Licensing boards and regulatory bodies process diploma submissions to verify that applicants hold qualifying degrees. Extracted fields such as institution name, field of study, and issuing date feed directly into licensing workflows, reducing review time for each application.
ATS & HRIS Integration via Workflow Automation
Connect diploma extraction results into your ATS, HRIS, or document management system using workflow automation tools like n8n, Zapier, or Make. When a new hire uploads their diploma, ByteIt extracts the credential data and pushes it to the employee record without any manual data entry.
LIVE DEMO
Try Diploma Extraction Yourself
Upload a sample diploma in PDF, JPG, or PNG format and see the extracted fields appear in real time.
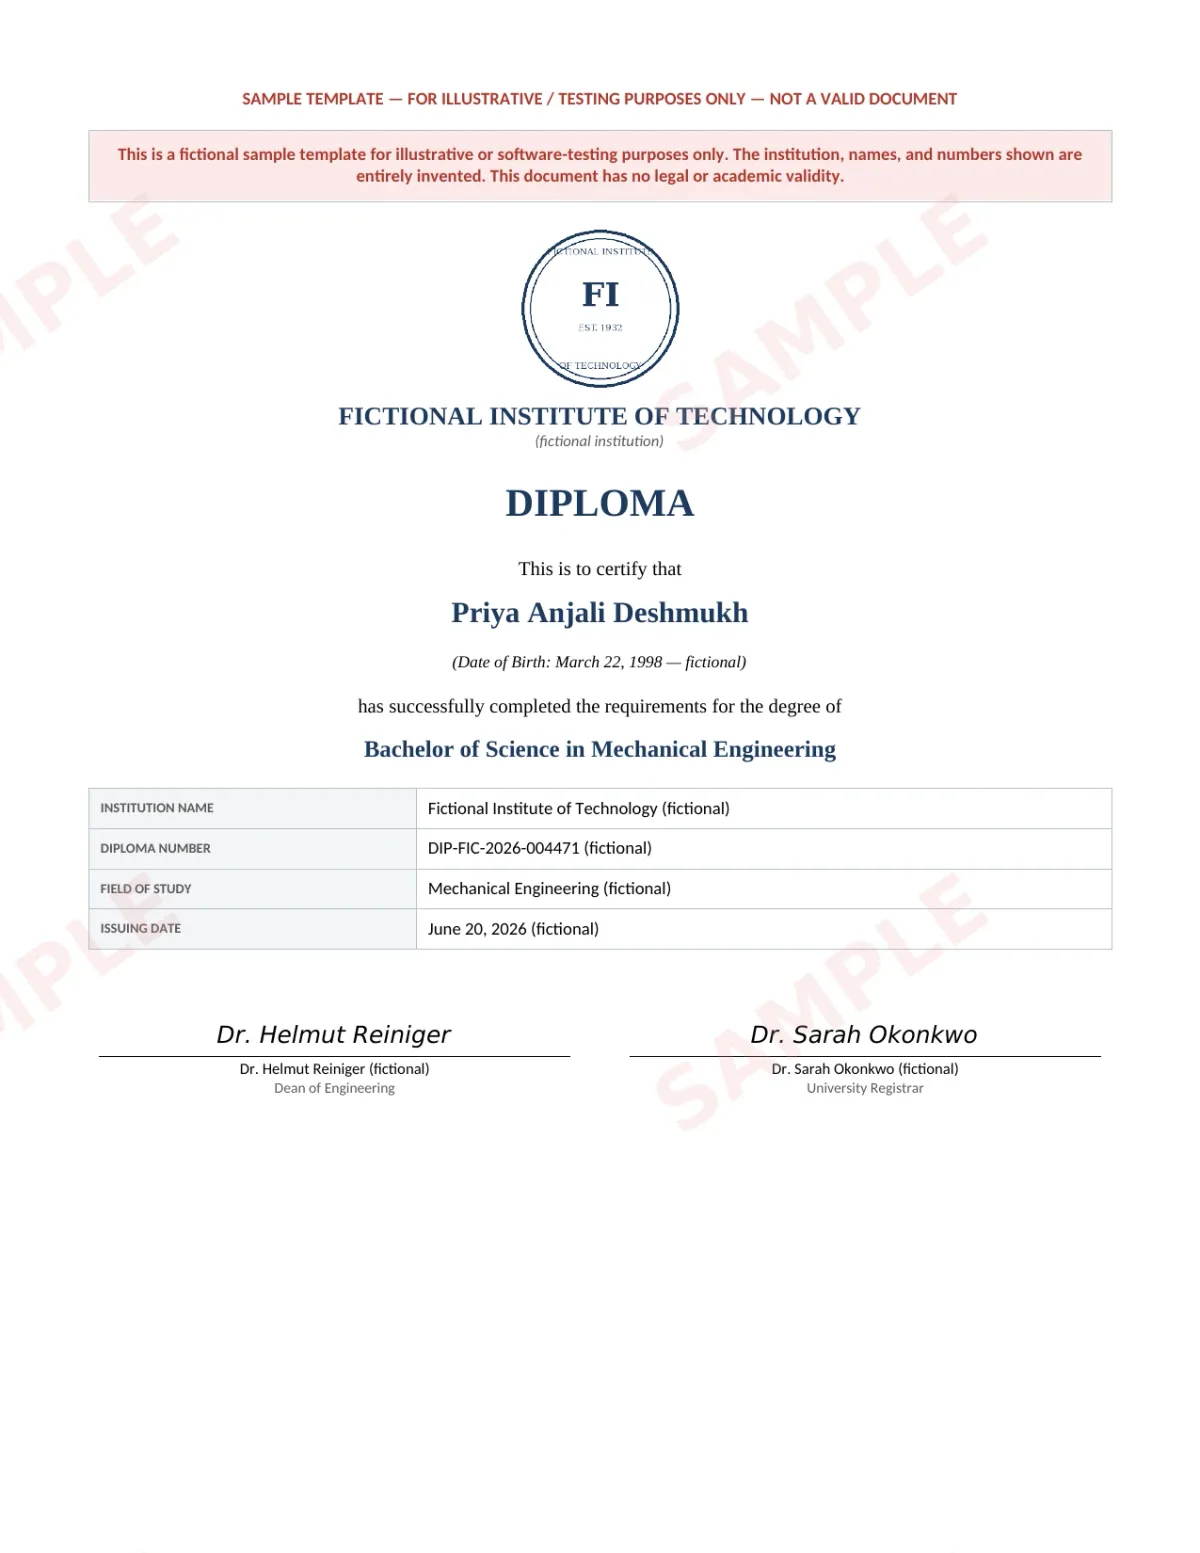
Select a document and press Parse
Want to run it on your own documents?
Ready to integrate? Get your API key in Studio.Business advantages
- Simple API with one call to extract all diploma fields
- Pre-built SDKs in Python, Node.js, Java, and more for rapid integration
- Flexible pricing tiers that scale with your document volume
- ISO 27001 certified and GDPR-compliant for handling sensitive academic data
Frequently asked questions
What file formats are supported for diploma extraction?
ByteIt accepts PDF, JPG, and PNG files. Both digital certificates and scanned paper diplomas are supported, including documents with stamps, seals, and institutional logos.
Does it work with low-quality scans or old, faded diplomas?
Yes. The extraction engine is trained on a wide range of document qualities, including faded ink, skewed angles, and archive-quality scans. Results are best with documents where the text is still legible to the human eye.
What fields can the API extract from a diploma?
Key fields include graduate name, date of birth, institution name, diploma number, issuing date, field of study, and institution logo. The engine surfaces structured JSON output for all detected fields.
How do I integrate the diploma extraction API into my workflow?
ByteIt provides REST API endpoints and SDK libraries for Python, Node.js, Java, and other languages. You can also connect the extraction output to your ATS or HRIS using no-code automation tools like n8n, Zapier, or Make.
Can the API handle multi-page diploma documents?
Yes, ByteIt supports multi-page PDFs. The engine processes each page and aggregates the extracted fields into a single structured output, capturing information that may span across pages such as degree details on one page and issuing signatures on another.
How is pricing structured for diploma data extraction?
ByteIt offers usage-based pricing with tiers designed for different volumes. You pay per document processed, with higher-volume plans offering lower per-document rates. Contact our sales team for a quote tailored to your expected monthly volume.
What languages and character sets does the diploma OCR support?
The engine supports Latin-based scripts commonly found in European, US, and international diplomas. For diplomas containing non-Latin scripts (Arabic, Cyrillic, CJK), contact ByteIt to discuss language-specific model support.
Related documents
Resumes Cv
Extract structured data from resumes and CVs in a wide range of layouts and languages. Parse names, contact details, work history, education, and skills with AI-powered accuracy.
Motivational Letter
Extract key fields from motivational letters automatically using ByteIt's AI-powered OCR API. Names, dates, language quality, and more. Reduce manual screening effort.
Employer Statements
Extract key fields from employer statements with AI-powered OCR. Automate HR data entry from salary, working hours, contract terms and more.
Proof Employment
Extract employee name, company name, salary, start date and more from proof of employment documents. AI-powered OCR API for HR automation.